Immutable Usage Event Logs as the Foundation of Billing Auditability
Immutable logs become the essential evidence when customers dispute usage charges.
Usage-based pricing has become the default architecture for how software gets sold, and that shift has quietly turned a back-office logging decision into a matter of customer trust. The share of SaaS companies using some form of usage-based pricing rose from roughly 30% in 2019 to about 85% by 2024, and hybrid pricing, meaning subscription plus consumption, jumped from 27% to 41% adoption in a single twelve-month stretch Flexprice. The majority of invoices landing in customer inboxes right now carry at least one line item that isn't fixed, isn't predictable, and depends entirely on a system somewhere having recorded what actually happened.
Customers have noticed, and they aren't happy about it. This isn't a minor irritation that gets absorbed into renewal conversations.
This mechanism produces the effect described above, and the usage event log confirms it. When a customer disputes a consumption charge, there's exactly one record that can settle the argument: the usage event log that generated the metered total feeding the invoice. If that log is incomplete, mutable, or simply untrustworthy, the dispute has no path to resolution, regardless of how good the vendor's customer support team is. Usage-based pricing aligns price with value delivered. That is why it has won the market. But it also does something less discussed: it transfers the burden of proof onto the vendor. Every variable invoice is, structurally, a claim, and a claim requires evidence. What follows is an account of what that evidence has to look like, architecturally and operationally, to actually hold up. The customer experience of variable charges is already strained, as 78% of IT leaders report unexpected charges from consumption-based or AI pricing models and 90% of CIOs cite cost forecasting as their top challenge Flexprice. Zylo's survey found 61% of organizations cut projects or initiatives because of unplanned SaaS cost increases in the past 12 months, showing the scale of financial surprise is large enough to terminate vendor relationships.
What an immutable usage event log is
An immutable usage event log is not simply a record that something happened. For each event, it has to capture the event type, the specific entity ID affected, the before and after state of every field that changed, a UTC timestamp down to the millisecond, the identity of the actor (a user ID, a service account, or an originating IP), and a request ID tying the record back to the exact API call or job that triggered it. Failed operations belong in there too.
Most billing systems fall well short of this. The weakest version, and it's disturbingly common, is a plain database audit table with no write protection, where a database administrator holding DELETE privileges can quietly erase rows. That might be tolerable for debugging logs. It is not tolerable for a financial record that a regulator or an auditor might ask to see. Audit logs are not the same category of thing as application logs, metrics, or traces. They are structured, append-only records built specifically for accountability and, when it comes to it, legal defensibility.
The flight recorder analogy holds up well here. A flight recorder is valuable precisely because nobody, not the pilot, not the airline, not the manufacturer, can edit it after the fact. A billing log that can be modified after the event is a draft, subject to revision. It's a draft, subject to revision, and therefore worthless as evidence. For AI products where credit consumption happens at millisecond speed, this isn't an abstract concern. The gap between a genuinely immutable log and a mutable audit table is the exact gap between an invoice you can defend in an audit and a dispute you simply cannot resolve.
The three-stage pipeline: how usage events travel from customer action to billable record
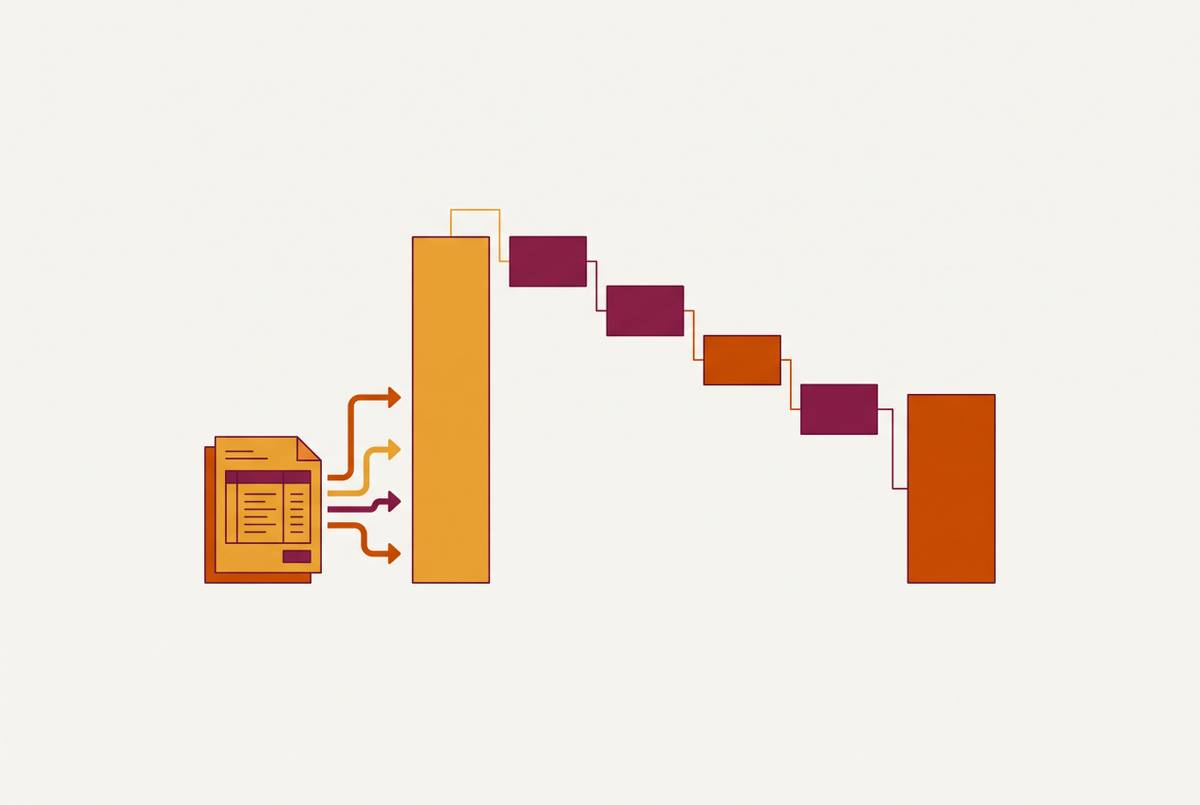
Getting from a customer's action to a line item on an invoice runs through metering and rating, in that order. Metering normalizes and aggregates the raw stream of events into billable metrics, such as gigabytes per month, token counts, or conversation counts. Rating then applies pricing rules to those metered numbers to produce an actual charge. It sounds simple written out that way. Getting it right at scale, with correctness guarantees a finance team can stand behind, is a different matter entirely.
Whether this works depends on the architecture choice between stream processing and batch. A stream processing setup ingests events off a message broker (Kafka, Kinesis, Pub/Sub are the common choices), applies stateful transformations as events arrive, and writes results into a billing state store with sub-second latency, which is what makes live spend alerts and hard credit-limit enforcement possible. Batch billing systems cannot do this, full stop, because their view of billing state is hours or days stale by construction. Kafka's log-based storage model helps here too: it retains every event for a configurable window, so consumers can replay from any point in time, which turns out to be essential when a billing system needs to reprocess history after a bug fix or a dispute investigation. Partitioning by customer ID keeps all of one customer's events flowing through a single consumer, which preserves order. Lose that ordering guarantee and the metered totals come out wrong, even when every individual event was stored correctly.
Agentic AI workloads make the stakes of pipeline latency concrete. Picture an AI agent running a multi-step workflow that throws off 3,000 events per minute. If the pipeline falls behind, enforcement starts reading stale state, the customer blows straight through their credit limit, and the metering layer only catches up an hour later, by which point the overage has already happened and already been charged. That's not a performance bug. It's a billing integrity failure with a customer-facing consequence attached. Which is why production billing pipelines set concrete recovery targets: a recovery time objective of one hour is the longest acceptable stretch before events stop being metered at all, and a recovery point objective of zero events, with no data loss acceptable, backed by multi-region replication, encrypted backups, and documented replay procedures. And scale isn't optional context here, it's a design constraint from day one: production billing event pipelines get engineered to handle over a million events per second, because retrofitting that capacity after launch is far harder than building for it up front.
Once events land, the question shifts from throughput to permanence: how they're stored and protected is where immutability either gets enforced for real or quietly abandoned.
How immutability is enforced at the storage and cryptographic layer
Storage-layer enforcement starts with write-once destinations. AWS S3 Object Lock and Azure Immutable Blob Storage both enforce immutability at the storage layer itself, independent of whatever the application logic does or fails to do. That independence is the point: even a compromised application, or a rogue engineer with production credentials, cannot rewrite what the storage layer refuses to let anyone touch.
Cryptographic chaining adds a second, complementary layer. Each log entry incorporates a hash of the entry before it, so any retroactive edit to history changes every hash that comes after it, making tampering detectable even on storage media that isn't intrinsically immutable. Secure hash functions like SHA-256 or Blake2, often paired with Merkle trees, support compact proofs of inclusion and efficient batch verification, so an auditor can confirm a single record belongs in the chain without having to review unrelated data. Digital signatures using schemes like ECDSA or Schnorr layer on non-repudiation, preventing anyone from forging a record after the fact and claiming it was always there. Publishing the chain's root hash to an external, independent system, a public blockchain, a trusted timestamping authority, a third-party audit service, gives cryptographic proof the log wasn't altered after a given publication date, and financial-sector audit systems already lean on this technique where regulators demand verification that doesn't depend on trusting the organization holding the log.
Database-level controls close the remaining gaps. That means revoking UPDATE and DELETE privileges on the audit table from the application role itself, so the application literally cannot issue those commands. A row-level trigger that raises an exception and blocks any DELETE attempt adds defense in depth against someone with elevated database access trying to route around the permission structure. Retention gets managed by dropping entire old monthly partitions rather than deleting individual rows, which respects immutability inside the retention window while still keeping storage costs sane. A workable canonical schema includes fields like event_id, occurred_at as a timestamptz, actor_type, actor_id, actor_ip, actor_ua, action, resource_type, resource_id, old_value and new_value as JSONB, and a metadata field, partitioned by range on occurred_at specifically to make monthly retention management tractable.
None of this works if the audit pipeline lives in the same database as the operational billing data. A single compromise of that shared database could let an attacker rewrite both the billing records and the very logs meant to hold those records accountable. Production architectures therefore route audit events through an asynchronous message queue into a dedicated, append-only audit store, separate from anything else. Access control follows the same logic: audit logs need tighter restrictions than the billing data they describe, so a support agent who can read an invoice should never be able to touch the log that generated it.
Point-in-time reconstruction: the forensic capability that turns logs into legal evidence
Storage-layer immutability is necessary, but it isn't sufficient on its own to answer the question that actually appears during an audit. A regulator or an external auditor doesn't ask whether a log exists. They ask something like: what did customer X's invoice look like on January 15, 2025, at 14:32 UTC? A billing system that only exposes current state has no way to answer that question with any confidence, because current state has already overwritten whatever was true at that moment.
Full before-and-after capture on every field is what makes an answer possible. It lets a system replay the change history up to any target timestamp, reconstruct exactly what the invoice looked like at that instant, and, critically, show which version of the pricing rules was actually active at the time, which matters enormously when pricing has since been updated. The operational cost of not having this is measurable: a Gartner report found organizations without comprehensive billing audit logs took an average of 4.3 times longer to resolve billing disputes than organizations with fully implemented audit trails. That's not a rounding error. A dispute closed in days versus one that drags on for months, burning support time and eroding customer patience the whole way through.
Revenue recognition standards depend on the same capability. ASC 606 under US GAAP and IFRS 15 both require records showing when performance obligations were actually satisfied, meaning when the service was delivered or the usage occurred, with enough granularity to support the timing of revenue recognition. External auditors sample billing records during financial audits and trace them back through the audit trail. A billing system that can't reconstruct point-in-time state fails that test, and failing it can force a revenue restatement, which is a considerably worse outcome than a delayed dispute resolution.
Whether a log entry exists is a different question from whether the record is complete and defensible. An audit rarely turns on whether something was logged at all. It turns on whether the logged record can withstand scrutiny, and a log that notes an event happened but can't reconstruct the surrounding context isn't evidence-grade, no matter how many rows it has. On the customer side, this same reconstruction capability is what powers usage dashboards that show a customer exactly what they consumed, when, and at what rate. A customer who can see that clearly is a customer who has far less reason to file a dispute in the first place.
Regulatory requirements that mandate immutable billing logs and their retention terms
Several overlapping frameworks require some version of this architecture, each from a slightly different angle. SOC 2 Type II requires logging of security events tied to whatever trust service criteria are under evaluation, which typically covers all user access to billing data and all changes to billing configuration. ISO 27001 mandates an information security event log as part of its Annex A controls. ASC 606 and IFRS 15, already mentioned above, require that companies keep records supporting revenue recognition timing, with enough detail on when usage actually occurred to back up that timing.
By 2026, immutable audit trails have stopped being a checkbox exercise and become a genuine prerequisite for operating in regulated markets, high-value enterprise agreements, remote onboarding flows, and any workflow with a plausible path to an audit, arbitration, or courtroom. That's a meaningful shift in framing. It's closer to table stakes for being allowed into the conversation at all. The stakes are large enough to justify that shift: financial fraud costs the global economy an estimated $442 billion annually, and immutable usage event logs function within that picture as a genuine risk-management instrument, not merely paperwork for an auditor's checklist Immutable Payment Audit Trails: Storage, Discovery, and Audits.
None of these frameworks tell an engineering team how to build the thing. They specify what to retain and for how long, but they stay silent on cryptographic implementation. Hash chaining, write-once storage, a separated audit pipeline, none of that is mandated by name in any compliance document. Those are engineering decisions a team has to make to satisfy the spirit of the requirement, since the letter of the requirement doesn't get anywhere near that specific. That gap is exactly where the weak, mutable audit table from earlier in this piece manages to survive for so long inside otherwise "compliant" organizations. And it's exactly why on-premises and sovereign cloud deployments face the same underlying requirements as cloud-native ones: billing infrastructure that can't enforce immutability in an on-prem configuration gets disqualified from regulated enterprise deals before evaluation even starts.
Operational querying, idempotency, and duplicate or out-of-order event handling
Immutability at the storage layer solves one problem and leaves another one sitting right next to it. A log that faithfully preserves every event forever is worthless if duplicate events double the metered charge, or if late-arriving events get dropped and never counted at all. Storage integrity and event-level correctness are separate engineering problems, and both have to be solved for the invoice at the end of the pipeline to actually be right.
Idempotency keys are the primary tool for handling duplicates. Ordering gets handled through the partitioning scheme discussed earlier: keeping all of one customer's events flowing through a single consumer by partitioning on customer ID preserves the sequence those events need to be processed in, and disordered events produce wrong aggregated totals even when each individual record was stored perfectly. Backpressure matters too. When a downstream system starts lagging, the ingestion layer needs to slow down gracefully rather than letting queues grow without bound, because unbounded queue growth turns a pipeline delay into both a data integrity problem and a live customer-facing enforcement failure at the same time.
None of this matters if the log can't actually be queried when someone needs it. An audit log has to support pulling every action tied to a specific resource, every action taken by a specific actor across a given window, and full point-in-time state reconstruction on demand. A log that technically satisfies a compliance checklist lets a dispute drag on, while a log a support team can actually use closes a dispute in an afternoon instead of a quarter. Everything covered here, hash chains, write-once storage, partition-preserved ordering, idempotent ingestion, exists in service of that one operational moment: someone asks what happened, and the system has a real answer. Idempotency keys, keyed on a stable event ID, serve as the primary mechanism for exactly-once accounting under at-least-once delivery, so that the same event arriving twice produces only one billable record.